Social Media Programming Especially Focusing on Google,Twitter and Facebook

Abstract

Our contemporary society calls the 21st century – “the century of data” and they are completely correct in making that observation. The present proposal goes beyond the revelations of the 21st century. It is proof of how far the spread of data can go.

Web-based social networking has changed how programming engineers team up, how they facilitate their work, and where they discover data. Online networking locales, for example, the Question and Reply (questions and answers) entry Stack Flood, re-write the files with many sections that add to what we think about programming advancements, covering an extensive variety of subjects. For now, product engineers, reusable code scraps, basic use cases, and appropriate libraries are regularly only a web seek away.

In this position article, we talk about the opportunities and difficulties for programming designers that depend on web content curated by the group, and we imagine the fate of an industry where singular engineers benefit from and add to a collection of learning, kept up by the group utilizing web-based social networking.

While the Web has provided a limitless source for learning, which is available to programming engineers, it is the progress of online networking that has presented powerful components for an extensive horde of designers to minister content on the web.

Clients can support articles through features like, for example, Facebook “Likes”, and they can give positive or negative appraisals to inquiries and replies on questions and answers sites, while also being able to comment on and remark on a wide range of blog entries. Content via web-based networking media locales, ranges from instructional exercises, and experience reports in order to code pieces and tests.

The phenomenon that is discussed later is namely social media programming especially focusing on Google, Twitter and Facebook. In order to derive better results we selected particular social media platforms – Google, Twitter and Facebook.

During further research, we have conducted surveys on social media programming. Also, tutorials have been done on Facebook programming and twitter programming with the help of examples.

A final conclusion has been made by comparing these two platforms from the point of view of the programmer.

A Study on Employee Safety and Welfare Measures Project Synopsis

SYNOPSIS

Wellbeing and Welfare is the principle sympathy toward the representatives. Minor ignores may likewise bring about irreversible risks. Consequently, the breakdowns in everyday exercises ought to be checked in each capacity. A domain ought to be made with the end goal that the representatives work courageously, concentrating on their work as opposed to wellbeing issues.

Welfare measures ought to be received by the associations in an approach to take most extreme care of the representative and its family, on the off chance that anything happens. Association ought to make an endeavor to make its partners mindful of all the related issues. This thus will enhance the representative profitability and effectiveness. Hierarchical concentrate on worker security can accommodate higher assurance and profitability in the working environment. This is because of the observation that the organization genuinely thinks about the wellbeing and prosperity of its representatives, consequently making a feeling of pride for the association. Expanded profitability as it connects to wellbeing and resolve is a troublesome metric to gauge, however ground breaking associations understand that it does exist and can in this way legitimize the expenses of their security programs when contrasted with the efficiency benefits that they give.

As opposed to measuring profitability as it identifies with wellbeing, the circuitous expenses of representative wounds are significantly more quantifiable. For instance, a passing or extreme harm at work site can close down a venture for expanded timeframes while it is under scrutiny, and lost time meets lost cash. Also, there is the cost of lost profitability of the influenced representative, expanded protection premiums, cost of supplanting the harmed specialist, cost of preparing the new laborer and potential fines. These expenses can be severe to the point that they may make it hard to run a gainful association. The previously mentioned focuses remain as inspiration elements to attempt the present review. Likewise suitable targets are confined and contemplated utilizing essential and auxiliary information.

This paper highlights the welfare measures taken in the Concrete company, the representatives’ fulfillment level, and to recognize the general nature of work life of the representatives. The Data accumulation was done through calendar. Now and again individual meeting was required at the season of topping off of survey. To examine, the gathered information we utilized basic rate investigation, one way ANOVA and Chi-Square test. Diverse diagrams and charts were attracted to decipher the gathered information.

Topic chosen for the study

My topic for study is “A study on employee safety and welfare measures provided at Concrete company”.

Worker welfare implies anything accomplished for the solace and change of the representatives far beyond the wages paid which is not a need of the business. The essential motivation behind representative welfare is to advance the life of workers and keep them glad. Representatives invest at any rate a large portion of their energy at work or getting to it, or abandoning it. They realize that they add to the association when they are sensibly free from stress and they feel that when they are stuck in an unfortunate situation/issues, they are expected to get something once again from the association. Individuals are qualified for be dealt with as full people with individual needs, trusts and tensions.

I found it interesting to check what measures Concrete company takes to ensure their employee safety and welfare. Hence, I opted for this topic.

Need For the Study

Security and Welfare is the fundamental sympathy toward the representatives in any association. Minor dismisses may likewise bring about irreversible perils. Henceforth, the glitches in everyday exercises ought to be checked in each capacity. A situation ought to be made with the end goal that the representatives work bravely, concentrating on their work instead of wellbeing issues. Welfare measures ought to be received by the associations in an approach to take most extreme care of the representative and its family, in the event that anything happens. Association ought to make an endeavor to make its partners mindful of all the related issues. This thusly will enhance the representative profitability and proficiency. Authoritative concentrate on representative wellbeing can accommodate higher spirit and efficiency in the work environment. This is because of the discernment that the organization really thinks about the wellbeing and prosperity of its representatives, in this manner making a feeling of pride for the association. Expanded profitability as it associates to wellbeing and confidence is a troublesome metric to quantify, however ground breaking associations understand that it does exist and can in this way legitimize the expenses of their security programs when contrasted with the efficiency benefits that they give. As opposed to measuring efficiency as it identifies with wellbeing, the aberrant expenses of worker wounds are considerably more quantifiable. For instance, a passing or extreme damage at work site can close down a venture for expanded timeframes while it is under scrutiny, and lost time measures up to lost cash. Furthermore, there is the cost of lost efficiency of the influenced representative, expanded protection premiums, cost of supplanting the harmed laborer, cost of preparing the new specialist and potential fines. These expenses can be severe to the point that they may make it hard to run a gainful association. The previously mentioned focuses remain as inspiration components to attempt the present review. In like manner fitting goals are encircled and considered utilizing essential and optional information.

Additionally, to realize that whether welfare offices assume a vital part on the working of representatives. Representatives assume a critical part in the mechanical generation of the nation. Subsequently, associations need to secure the participation of workers so as to expand the generation and to acquire higher benefits. The participation of representatives is conceivable just when they are completely happy with their manager and the working conditions at work. Previously, industrialists and the businesses trusted that their lone obligation towards their workers was to pay them agreeable wages and compensations. 

Objectives of the Study

  1. To comprehend the consciousness of wellbeing and welfare offices among the workers gave by the association.
  2. To discover the use of welfare offices by the workers
  1. To discover the level of fulfilment of workers concerning work welfare offices.

Scope of the Study

This survey arrangements to find the satisfaction of the delegates, whether the association is giving basic prosperity, security and welfare measures in Concrete company. The degree of the present audit named” Employee Safety and Welfare Measures” is restricted to Concrete company.

Methodology

Research is customary discourse suggests a request of learning. It can be portrayed as consistent and orderly output for related information on a specific errand. Infact, research is a specialty of coherent examination. The moved learner is registry of back and forth movement English which sets out the significance of research as a careful examination or demand especially through output for new sure nesses in ones pined for branch of data.

Explore philosophy is an approach to efficiently take care of an examination issue. It might be comprehended as a study of contemplating how research is done logically. In research it is the duty of the analysts to uncover the exploration choices and to assess them before they are actualized. The scientist has indicated plainly and definitely, what choices is and why the choice is made, so others can assess it.

Research Design

An exploration configuration is the course of action of conditions for gathering and investigation of information in a way that expects to join pertinence to the examination reason with economy in methodology. The analyst has embraced an unmistakable kind of research, It portrays the qualities of populace or presentation of respond in due order regarding the inquiries like where, when and how identifying with a specific field. The review will exhibit the situation as it exists. This kind of study for the most part knows the past and to anticipate what’s to come. 

Data Collection Method

While managing any genuine issue, clearly information are insufficient and henceforth it gets to be distinctly important to gather information that are proper. Contingent on the wellsprings of data accessible information can be delegated Primary information, Secondary information. Information was gathered specifically from the respondents through polls, individual meetings and exchanges with authorities and supervisor at Concrete company. The reactions of the representatives towards laborer “wellbeing and welfare” measures in the association is examined utilizing fitting factual instruments which can be found in Levin and Rubin (2000). 

Sample Size

The sample size for the study is 100 employees in Concrete company. 

Limitations of the study

The review has the accompanying confinements. Representatives were hard in a rush in perspective of the occupation requests, and thorough work routines. Thus, the scientist needs to induce them for saving time for reacting to the polls and meetings. When he found that the respondents were not ready to invest satisfactory energy for the reason, he needed to demand them to dispense time after the move timing indeed, building up affinity with the respondents represented an issue at first.

Understanding Big Data – In the Context of Internet of Things Data

Executive Summary

This Knowing Internet of Things Data: A Technology Review is a critical review of Internet of Things in the context of Big Data as a technology solution for business needs. It evaluates the potential exploitation of big data and its management in correlation to devices which are Internet of Things. The article begins with literature review of internet of things data, thereby defining it in academic context. It then analyzes big data usability in commercial or business economics context. It discusses and evaluates the application of Internet of Things Data which ensures there is value-addition to a Business. The main objective of this Knowing Internet of Things Data: A Technology Review is to communicate the business sense or the business intelligence in use of big data by an organization. The premise of paper, is that, Internet of things data is an emerging science with infinite solutions for organizations to exploit and build services, products or bridge ‘gaps’ in delivery of technology solutions. The possibilities of using big data for marketing, healthcare, personal safety, education and many other economic-technology solutions are discussed.

Introduction

Organizational decisions are increasingly being made from data generated by Internet of Things (IoT), apart from traditional inputs.  IoT data is empowering organizations to manage assets, enhance and strengthen performances and build new business models. According to MacGillivray, C., Turner, V., & Lund, D. (2013) the number of IoT installations is expected to be more than 212 billion devices by 2020. Thus, management of data becomes a crucial aspect of IoT, since different types of objects interconnect and constantly interchange different types of information. The scale or volume of data generated and the processes in handling data are critical to IoT and requires the use several technologies and factors.

Addressable market area globally for IoT is estimated to be $1.3 trillion by 2019. New business opportunities are thus plenty, allowing organizations to become smarter and enhance their product, services and improve user/customer experience, thereby creating Quantified Economy. According to Angeles et al ( 2016) (1) Internet of Things spending is $669(2) smart homes connectivity spend $174 million (3) Connected cars by 2020 spend $220 million.  The has led to companies revisiting their decisions (1) Are services or products of their organization capable to connect or transmit data (2) Are the organizations able to optimize value from the data they have (3) Are the connected devices at the organization able to provide end-to-end-view (4) Do organizations need to build IoT infrastructure or just parts of a solution to connect devices.  Some examples of IoT and business value – (a) real estate holding company adopts smart buildings networking for ‘real-time’ power management and save substantially on expenses incurred in this sector (2) incorporating sensors in vehicles allows logistics companies to gain real-time input on environmental, behavioural factors that determine performance (3) Mining companies can monitor quality of air for safety measures and protecting miners.

Hence, the immediate results of IoT data are tangible and relate to various organizational fronts – optimize performance, lower risks, increase efficiencies. IoT data becomes the vital bridge for organizations to gain insight and strengthen core business, improve safety and leverage data for business intelligence, without having to become a data company itself. Organizations can continue to focus on their deliverables instead of the backend of generating value from data, by using several IoT data management, storage technologies offered by vendors competitively.

Algorithm Marketplaces

As big data enters the ‘industrial revolution’ stage, where machines based on social networks, sensor networks, ecommerce, web logs, call detail records, surveillance, genomics, internet text or documents generate data faster than people and grow exponentially with Moore’s Law, share analytic vendors.  Therefore, virtual marketplaces where algorithms (code snippets) are purchased or sold is expected to commonplace by 2020. Gartner expects three vendors to dominate the market place and are all set to transform the software market of today, with analytics domination. Simply said, algorithm marketplace improves on the current app economy and are entire ‘’building blocks” which can be tailored to match end-point needs of the organization. (1) Granular software will be sold in more quantities, since software for just a function or a feature will be available at cheap prices. (2) Access to powerful, advanced, cutting-edge algorithms by inventors who earlier restricted their products in-house are now commercially made available, widening application scope and benefitting businesses. (3) reuse or recycling of algorithms is now optimized. (4) quality assessment optimized.

Model Factory

Data storage is cheap and hence can be mined for information generation.  Technologies such as MPP (massively parallel processing) databases, distributed databases, cloud computing platforms, distributed file system, as well as scalable storage systems are in use.  Using open source platforms such as Hadoop the data lake built can be developed to predict analytics by adopting a modelling factory principle. In this technology, of which there are several vendors, the data that an organization generates does not have to handled by data scientist but focus on asking right questions with relation to predictive models. The technology allows real automation to data science, where traditionally work was moved from one tool to the next, so that different data sets were generated and validated by models. The automation of such processing not only removes human error but also allows managing hundreds of models in real time. In model factories of the future, software will pre-manage data and scientists have to concentrate only on how to run models and not iterate their work. Model factories of the future are the Google and Facebook of today, but without the number crunching army of engineers but automated software to manage data science processing via tooling and pervasiveness of machine learning technologies. Examples include Skytree.

Edge analytics

Business environment creates unstructured databases which could exceed zettabytes and petabytes and demand specific treatment in terms of storage of processing and display.  Hence, large data-crunching companies such as Facebook or Google cannot use conventional database analytic tools such as those offered by Oracle as big repositories require agile, robust platforms based on either distributed, cloud systems or open source systems such as Hadoop. These involve the use of massive data repositories and thousands of nodes which evolved from tools developed by Google Inc, like the MapReduce or File Systems or NoSQL. None of these are compliant with conventional database characteristics such as – atomicity, isolation, durability or consistency.  Hence to overcome the challenge data scientists collect data, analyze it by using automated analytic computation on data at a sensor or the network switch or other device and does require that data is returned to data store for processing. Thus, by annotating and interpreting data, network resources mining of data acquired is possible.

Anomaly detection

Data Scientists use the outlier detection or anomaly detection process to identify instances or events which fall short of a template pattern of an item on a data set. In short, they are the set of data points which are different in many ways from the remainder of the data. These are used in credit card frauds, fault detection, telecommunication frauds, network intrusion detection. This also used statistical tools such as Grubbs’ test to detect outliers or univariate data (Tan, P. N., Steinbach, M., & Kumar, 2013).

Event streaming processing

ESP or Event Stream Processing is described as the set of technologies which are designed to aid the construction of an information system that are event-based. Thus, this technology include – event visualization, event databases, event driven middleware, event processing languages as well as complex event processing. Here data that is collected is immediately processed without a waiting period, and creates output instantaneously.

Text analytics

Text analytics refers to text data mining and uses text as the units for information generation and analysis. The quality of information derived from texts is optimal as patterns are devised and trends are used in the form of statistical pattern leaning.  Unstructured text data is processed to form meaningful data for analysis so that customer opinions, feedback, product reviews are quantified. Some of the applications here are sentimental analysis, entity modelling support for decision making.

Data lakes

Data lakes are storage repositories of raw data in its native format. These are held in this state, until they are required. Such storage is done in a flat architectural format and contrasts with that ot data stored hierarchically in data warehouse stores. Data structures are defined only when the data is needed. Vendors include Microsoft Azure, apart from several open source options.

Spark

Spark is a key application of IOT data which simplifies real-time big data integration for advanced analytics and uses realtime cases for driving business innovation. Such platforms generate native code and needs to be further processed for Spark streaming.

Conclusion

According to Gartner as many as 43% of organizations are committed to invest and implement IoT, and is indicative of the massive scale of data the organizations will come to generate. Thus, utilities or fleet management or healthcare organizations, the use of IoT data will overturn their cost savings, operational infrastructure as well as asset utilization, apart from safety and risk mitigation and efficiency building capabilities. The right technologies deliver on the  promise of big data analytics of IoT data repositories.

References

Angeles, R. (2016). STEADYSERV BEER: IOT-ENABLED PRODUCT MONITORING USING RFID. IADIS International Journal on Computer Science & Information Systems, 11(2).

Chen, H., Chiang, R. H., & Storey, V. C. (2012). Business intelligence and analytics: From big data to big impact. MIS quarterly, 36(4), 1165-1188.

Fredriksson, C. (2015, November). Knowledge management with Big Data Creating new possibilities for organizations. In The XXIVth Nordic Local Government Research Conference (NORKOM).

MacGillivray, C., Turner, V., & Lund, D. (2013). Worldwide Internet of Things (IoT) 2013–2020 Forecast: Billions of Things. Trillions of Dollars, Gartnet Market Analysis.

Tan, P. N., Steinbach, M., & Kumar, V. (2013). Data mining cluster analysis: basic concepts and algorithms. Introduction to data mining.

Troester, M. (2012). Big data meets big data analytics: Three key technologies for extracting real-time business value from the big data that threatens to overwhelm traditional computing architectures. SAS Institute. SAS Institute Inc. White Paper.

K-means clustering and DBSCAN Algorithm implementation in R

K-means clustering and DBSCAN algorithm implementation. The below work implemented in R

1. Implement k-means algorithm in R (there is a single statement in R but i don’t want. that) and need complete algorithm will should run according to ocean data set variables. It is a time series data.

2. implement DBSCAN algorithm in R.
Here the result will be a clusters. by user defined k and based distance values…
And finally the two algorithm results compare and correlate..

NOTE: These two algorithms are very simple and well known too.

Goal of the work:

K-Means Algorithm:

1.Implement k means algorithm for ocean data set( the data set it contains input variables like sea surface temperature, water temp depth at meter level,wtd20m wtd30,……etc)

Based on Distance calculations equations (i.e Equaliden distance, Menhaten distance) the clusters are formed it is algorithm logic. It is there in R already implemented in two dimension..(X axes and Y axes)

Write a code for three dimension (X-axes,Y-axes,Z-axes)
that means if it is X-axes variables statement one is executed or of it is two variables statement two (X and Y axes )executed or three variables (X,Y,Z axes) statement executed.
note: Every statement result will be stored in object
and that what ever the cluster we got according to algorithm it could be displayed in graph.

2. implement DBSCAN algorithm based on algorithm steps.

finally the both results display in graph format.(for correlation)( for example it is like our cricket two innings score graph)

The above two steps are according to algorithms.

This Project is with the programming or the analysis. If you need the programming, It will be with the R codes and functions, where you can input any variable and get the results you desire. Else If we require the analysis, we have to specify which variables to include because, there are 145 variables in all, and no graph or clustering technique can deal with 145 variables at a time.

Based on results algorithms we can analyse so for that use sea surface temp,wtd depth in different levels and date variable finally sub surface temperature.

Note: The final goal is for analysis based on cluster formation (code results)
And the output of the clusters will be in visualize in image formation..

Related Questions:

1.How should the algorithms works for any ocean data? Is it run for all data sets?

2.How should we give input values for K-means and DBSCAN and where it is?

3.In the results there is no monthly representation in any of the axes.( example : if we give k=12 that shows 12 clusters, the entire data set divided into 12 clusters so if cluster 1 is red in colour you months in X-axeas for representations.

4 The results showing individual graphs in final.it is ok. But we also need both two results in single graph.

5. how should data set reads in that code? How should i give any of the variables for clusters.

6. Is that algorithms runs individual ? I need individual execution.

Please use the R file named “Rmodified” that i sent with the instructions in a zip
Secondly any cluster plot displays distance matrix, in 2D and not clusters on basic scatter plot. however after running the codes, with the same variables as in the video, run these 3 commands, and you will get a scatterplot with the clusters of different colours.
par(mfrow=c(2,1))
plot(a,col=c1$Kmeans,main=”K means”)
plot(a,col=c1$dclus,main=”DB SCAN)
but in 3d, we don not get distances, because a 3 dimensional distance is basically of no use. hence in 3d we get a 3d cluster plot

It is made to deal with missing values

to enter from a CSV file use a variable, say file, to store the CSV file.
file=read.csv(“path of file”, header=T)
then extract the variables from the file
x=file$”input the column name of 1st variable you want”
y=file$”input the column name of 2nd variable you want”
then
a=as.matrix(cbind(x,y),ncol=2) and then the usual method.

and between i am using 3.2.2

Answers:

1. The data will work for any data set and any set of variables.

2. All instructions are given below

3. Please follow instructions

4. Overlaying the same variables with different cluster method on a single graph is not possible.
This is because, suppose a point is marked as red according to a cluster of DBSCAN,now if it has to represent a cluster of kmeans then it should have a different colour according to the kmean clusters. This is a contradinction as a point can be of only one colour at a time. Again if the point is red according to both clusters, then how can you differentiate between the two cluster methods? You can search the web for reassuarance.

5.Follow instructions
6.Follow instructions

This is a custom function in R, and works like any other functions that you use in R like mean(), sd(), kmean() etc
However as this is custom, you need to run the algorithm before you can apply the function.I have simplified it further for your convinience

Firstly download the graphics packages, if you do not have them already :
1. dbscan
2. rgl
3. cluster

to download go to packages -> install packages -> select CRAN server -> search and click from the list of packages

Secondly, run the code except for the last line that states cluster(…)

Now, you are ready to use the function named cluster that i defined. It has a set of parameters.
However you need to follow the order of the parameters as this is a custom function.

the first parameter in the function is a matrix. this is where you put your variables after converting them to matrix.
to convert to a matrix simply use as.matrix(cbind(x,y,z),ncol=3)
where x,y,z are the variables and ncol is the number of variables. you can use 1 or 2 or 3 variables as you require.
But if you put 4 or more, you will not get the graph, because R cannot produce graphs in 4 or higher order dimensions.

Next you have value of epsilon for DBscan
next Minimum points of DBSCAN
next the dimension of the matrix, i.e. number of variables combined into matrix
next you have number of clusters for kmeans
next you have Xaxis, Yaxis, and Zaxis labels for the graphs
and lastly you have the option of putting in any extra variable like months, years etc that will not be clustered,
but will be plotted against the X-axis.Howvever you can ignore this if you do not require it.

However,adding an extra variable with low correlation
will definitely take in another dimension of the graph. That means if you have 2 variables it will produce a 3d graph.
If you already have a 3, R cannot go further and hence will display error.

#####The Program being an custom one can take time to compute depending upon your conputer and data set.
it can take as long as 2 or 3 mins, so have patience.######

Here is an example,

cluster(x,2,3,2,5,”Xaxis”,”yaxis”,”zaxis”,y)
######please maintain the order of parameters and write it in the above format#########

However as this is not a default function, do not use it in this way
cluster(matrix=x,epsilon=2….) this is not right. The previous one is right.

To avoid compilation error, please do not skip any parameter except for the optional variable and name of zaxis when not required

You can also store the value of the function in a variable, and use specific information from it later
eg
a=cluster(….)
then
a$dbscan will display results of DBSCAN
a$dclus will give the cluster compositoin of DBSCAN
a$KMmean will give mean vector of K-means
a$Kclus will give cluster composition of Kmeans
a$Kmeans will display results of K-means
a$SSW will give the percentage of SSW as a part of TSS

The program prepared in R computes the clusters according to both the algorithms and then are displayed graphically for us to compare and analyse. However the number of K-mean clusters have been set according to the number of clusters formed in DBSCAN so as to ease the comparison. 

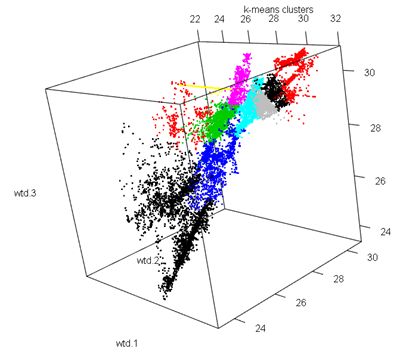
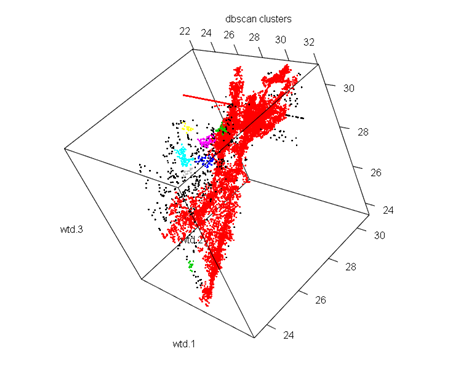
Clustering with wtd.1,wtd.2,wtd.3

DBSCAN

Parameters: eps = 0.2, minPts = 10

The clustering contains 10 cluster(s) and 491 noise points.

   0     1     2     3     4     5     6     7     8     9    10

  491 15152    29    44   100    64    18    18    11    10    14

The algorithm gives us 10 clusters. So as we see the clusters formed are not well distributed with the first cluster having the majority of the values while the remaining having very low values. However the clustering technique was quite decent because of the fact of such low noise.

K-means

Cluster Number No of elements

1              1                   3325

2               2                  303

3               3                 2334

4               4                 1610

5               5                  2869

6               6                   928

7               7                  371

8               8                 1349

9               9                 1704

10             10               1158

SSB as a percent Of TSS

86.43162

The clustering was quite good as 86%of the total variation is explained by the between cluster variation.

The K-means has even distributed clusters while in the DBSCAN clusters we see a majority of red points that indicate the 1st cluster with the maximum number of observations, and very few other colour points. In this case K-means was a better method as it was able to cluster the various segments of the dataset.

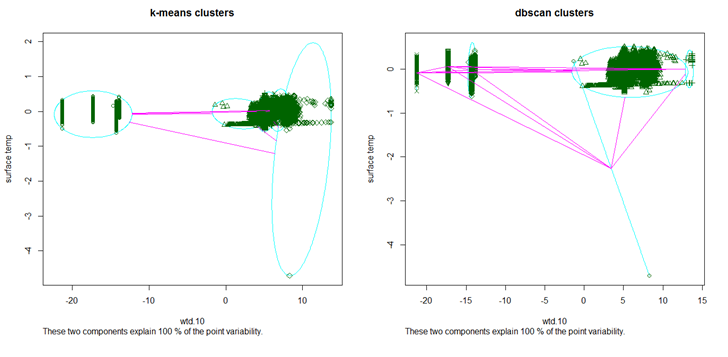
Clustering withwtd.10 and surface temp

DBSCAN

Parameters: eps = 0.8, minPts = 10

The clustering contains 5 cluster(s) and 2 noise points.

    0     1     2     3     4     5

    2 11406    46   620  2712  1165 

In this case we have 5 clusters, that are quite evenly distributed and more over the clustering was extremely good because of the presence of only 2 noises.

K-means

  Cluster Number No of elements

1              1                  4497

2              2                  933

3              3                  5158

4              4                  2796

5              5                  2567

SSB as a percent Of TSS

98.07178

Even in the case of K-means the clustering was very good for 98% of the total variation is explained by the between cluster variability. Moreover the clusters are evenly distributed.

The DBSCAN algorithm is a better method in this case as it has correctly identified the patters in the data, and has formed three separate clusters on the top left. However K-means has not done so well compared to DBSCAN because of the fact that it has formed 4 clusters in the densely populated area which could have been portrayed under one cluster.

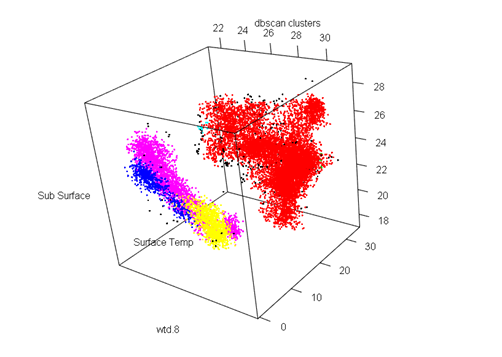
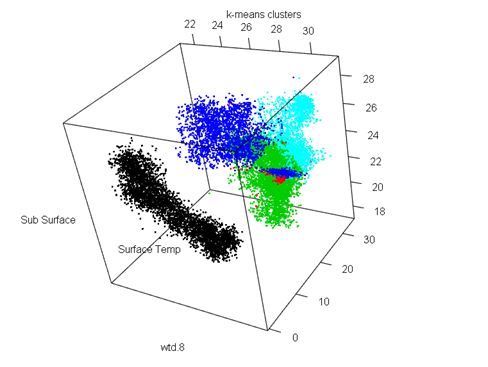
Cluster with wtd.8 and surface temp and sub-surface temp

DBSCAN 

Parameters: eps = 0.5, minPts = 10

The clustering contains 6 cluster(s) and 287 noise points. 

    0     1     2     3     4     5     6

  287 11156    18   611    14 2706  1159

 In this case we have 6 clusters with a decent number of noise.

K-means

Cluster Number No of elements

1              1                  4497

2              2                   100

3              3                  4737

4              4                  2936

5              5                  3650

6              6                   31

 SSB as a percent Of TSS

93.44828 

The clustering was quite good owing to the fact that 93% of the total variability was explained by the between cluster variance.

Both the algorithms were equally good in clustering the dataset. While k-means has clustered the broader region into three groups, DBSCAN has the clustered the more scattered region into three different sections.

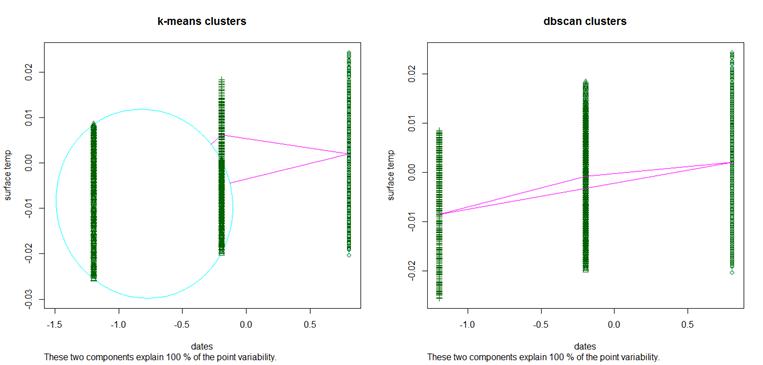
Cluster with dates and surface temp 

DBSCAN 

Parameters: eps = 0.5, minPts = 10

The clustering contains 3 cluster(s) and 0 noise points. 

   1    2    3

5168 8731 2052 

            The algorithm has perfectly clustered the data with no noises. There are 3 broad clusters that are more or less evenly distributed.

K-means

  Cluster Number No of elements

1              1                  5168

2              2                  5627

3              3                  5156 

SSB as a percent Of TSS

80.2711 

K-means however shows a poor clustering, with only 80% of the total variability explained by the between cluster variability.

This is the perfect example where DBSCAN works better than K-means. If we look at the K-means graph we have one big circular cluster on the left and two relatively small clusters on the right. However DBSCAN was successful in identifying the 3 major clusters in the dataset.

Download K-means clustering and DBSCAN Algorithm implementation in R Project Source Code.

Paint Editor Application .Net Project

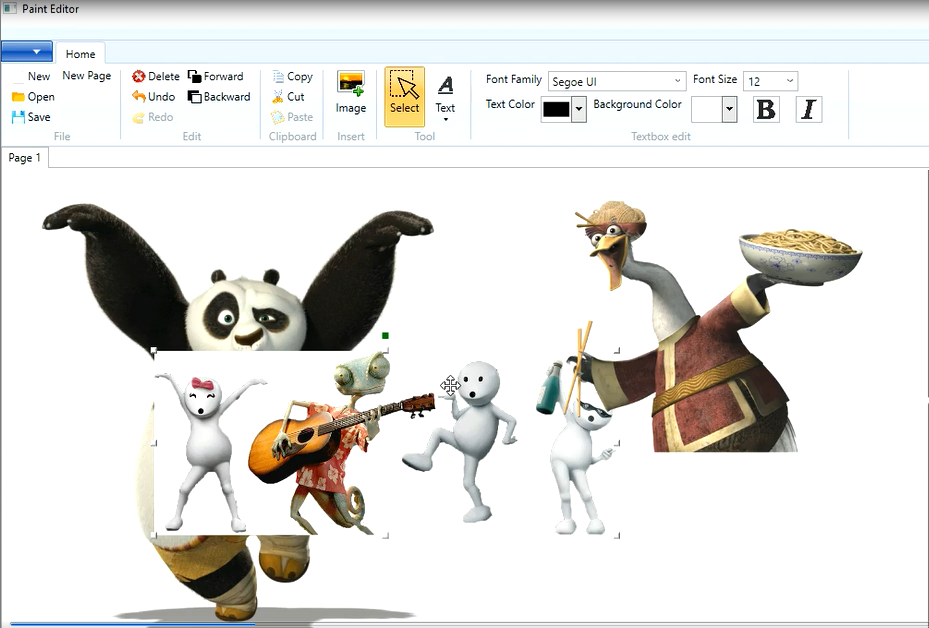
This is a Paint Editor Application tool where the user can create amazing designs on his own very easily.

In this editor/application with the following features This is similar to paint application but with the added features.

Features Below:

1. User will be able to create an empty page
2. On click of a text icon in tool box, User will be able to create the text at any place on the page.
3. On click of an img icon in tool box, User will also be able to import images on to the page.
4. On click of a ‘+’ icon in tool box, user will also be able to add new page.
5. User can do all the manipulations on the new page for text and images.
6. User will be able to duplicate the page on clicking the “duplicate page” button in toolbox.
7. User will be able to edit the text, move the text, rotate and be able to scale it.
8. User will be able to create multiple copies of the text.
9. User will be able to change the color of the text, by clicking on the text and choosing the color.
10. User will be able to change the font, style (like bold, italic), theme (TimesNewRoman, Calibri) of the text.
11. User will be able to browse through the local file system and select desired image and be able to import it onto the page.
12. User will have the ability to import multiple images on to the page.
13. User will also be able to make multiple copy/copies of the imported image.
14. User will be able to move, rotate, and scale the images.
15. User will be able to move the objects forward if there is another object on top of them. For eg: if there is a text on top of which there is an image. If user wants the text to be displayed on top of the image, he can select the text on click on fwd. button on top of the page.
16. User will be able to move the objects backward if there is another object on behind them. For eg: if there is a text behind an image and the user wants the text to be displayed on top of the image, he can select the image and click on bkd. icon on top of the page, to move the image backward.

Though the requirements seems to be very simple, we need to create a brand new Windows application using .NET and exhaustive testing needs to be done.

Technology: .NET

Contents of output package: exe of the developed application, clear documentation and readme file.

Introduction

1. Welcome to Paint Editor Application

2. It allows you to do major functionalities similar to paint application.

Configuration

1. Downloaded folder contains 2 files

2. Both should be placed in the same folder to run the application.

Modules:

1. Create New Page
2. Open

3. Save

4. Delete, Redo, Undo

5. Cut, Copy, Paste

6. Insert, Move, Scale, Rotate image files.

7. Insert, Move, Scale, Rotate Text.

8. Change Font Size, Font Family, Font Colour and basic font functionalities (Bold, Italic) for TEXT.

Download The Paint Editor Application .Net Project Source Code

A Study on Six Sigma Training Program with Reference to Selected IT Companies in Hyderabad

OBJECTIVES OF THE STUDY

  1. To study the impact of six sigma training program on service quality.
  2. To determine the satisfaction levels of the employees on the training program process using six sigma provided to them.
  3. To study the gaps in employees effectiveness before and after the six sigma training sessions conducted by the company.
  4. To find out measures to improve the quality of six sigma training program to be conducted on future employees.

Six sigma processes in the organization involves a lot of planning and efforts in order to be effective. Moreover, it includes huge costs. In order to know whether the six sigma program has met its objectives or not, the management needs to calculate its effectiveness. 

SCOPE OF THE STUDY

The study focuses on how the six sigma programs are being conducted in the organization and what is their effectiveness in improving the service quality.

The study being conducted on the six sigma methods followed by an organization, the scope is limited to one organization and its employees. The study collects the responses of the employees in the IT Companies at Hyderabad regarding their perceptions, satisfaction levels and impact on them.

The study focuses on the following factors in order to bring out the effectiveness of Six sigma.

  1. Frequency of the Six sigma programs
  2. Duration of the programs
  3. Selection criteria
  4. Feed back
  5. Objectives of the programs
  6. Support to the trainees
  7. Confidence level of trainees
  8. Relevancy of programs to individual needs
  9. trainer’s theoretical knowledge
  10. Level of freedom to the trainee

HYPOTHESIS:

Hypothesis 1:

Null hypothesis: There is no effectiveness of the training program using six sigma conducted by the company.

Alternative Hypothesis: There is a effectiveness of the training program using six sigma conducted by the company.

Hypothesis 2:

Null hypothesis: There is no significance impact of six sigma training program on the service quality.

Alternative hypothesis: There is a significance impact of six sigma training program on the service quality

Hypothesis 3:

Null hypothesis: There is no significance satisfaction levels of the employee on the training program using six sigma provided to them.

Alternative hypothesis:  There is a significance satisfaction levels of the employee on the training program using six sigma provided to them.

Hypothesis 4:

Null hypothesis: There is no significance whether employees are aware about their responsibilities and authorities in training program on six sigma or not.

Alternative hypothesis: There is a significance whether employees are aware about their responsibilities and authorities in training program on six sigma or not.

Sampling Design:

Sampling involves the procedures that use a small number of units of population to make conclusion regarding the whole population. The sampling design to be followed in this study is as follows.

  1. Sample frame: The sampling frame IT from among the employees working in IT Companies.
  2. Sample units: The employees working in IT Companies form part of the sample units.
  3. Sampling method: The simple random sampling method used to select the respondents
  4. Sample size: The sample size is limited to 100 employees working at IT Companies. 

The following companies IT taken as sample

The 20 The staff working in HR department of five selected IT companies such as TCS, Infosys, Tech Mahindra, IBM and Wipro form part of the Sampling units.

Data collection

The study is based mainly on primary data.

  • Primary data sources:

Primary data IT collected through the issue of questionnaire to the employees working at IT Companies.

  • Secondary Sources:

Secondary data is the data that collect from the historical/existing sources of data as databases, journals such as Articles, Journals, Magazines and Quality Management Text books, articles, research reports, websites related to six sigma and employees training methods.

Data Analysis: The data analysis IT done using suitable tables, charts, graphs, percentages and other suitable tools.

LIMITATIONS OF THE STUDY

  1. The study was done on  five  selected IT companies in Hyderabad
  2. The study is  limited for a period of one month
  3. The views and opinions of the respondents may change over the period of time
  4. The approach to six sigma training program may vary from company to company

DIRECTIONS FOR FURTHER RESEARCH:

The study can be further extended by including all the factors which are directly or indirectly affect the Six sigma. The company wants employees to be efficient in their approach in dealing with the customers. This study is a torch bearer for the upcoming  management students academicians and companies to know the application of six sigma in training programs undertaken by the company. This research has further scope in dealing with quality control programs on human resources of the company.

CHAPTER IV

DATA ANALYSIS AND INTERPRETATION

 How long have you been working in the current organization?

  1. Less than 6months
  2. 6-12months
  3. 1-2yrs
  4. 2-5yrs
  5. Above 5yrs

INTERPRETATION: From the above graph, we can notice that 28 respondents has been working in between 1 – 2 years, 26 respondents in between 2 – 5 years, 19 respondents above 5 years, 15 respondents 6 – 12 months and the remaining 12 respondents are less than 6 months.

How times has your organization  undergone six sigma as of now?

  1. Once
  2. 2 to 5 times
  3. 5 to 10 times
  4. More than 10 times

INTERPRETATION: From the above graph, we can notice that 46 respondents has undergone Six sigma in between 5 – 10 times, 25 respondents attended in between 2 – 5 times, 15 respondents attended only one time and 14 respondents attended more than 10 times.

What is the frequency of the Six sigma programs in your organization?

  1. Frequent
  2. Regular
  3. Occasional
  4. Rare
  5. Never

INTERPRETATION: From the above graph, 44 respondents as occasionally, 32 respondents as rarely, 16 respondents are regular, 6 respondents as frequently while 2 respondents that they never had a Six sigma programs in their organization.

Have you undergone any Six sigma in the last year?

  1. Yes
  2. No

INTERPRETATION: Among 100% respondents, 88% of the employees had undergone Six sigma in the last year 12 respondents are not undergone.

What is the duration of the Six sigma you have undergone?

  1. A week
  2. A month
  3. 1-3 months
  4. 3-6 months
  5. More than 6 months

INTERPRETATION: From the above graph, we can notice that 46 respondents has undergone Six sigma for 1 – 3 months, 22 respondents for 3 – 6 months, 14 respondents for a month, 10 respondents for more than 6 months and the remaining 8 respondents for a week.

What types of Six sigma have you undergone till now?

  1. On the job Six sigma
  2. Off the job Six sigma
  3. Both

INTERPRETATION: According to the pie chart, it is observed that 49% has gone for off the job Six sigma and 16% has undergone on the job Six sigma while 25% has taken both the Six sigma.

What is your level of satisfaction with the duration of Six sigma programs?

  1. Highly satisfied
  2. Satisfied
  3. Neither satisfied nor dissatisfied
  4. Not satisfied
  5. Not at all satisfied

INTERPRETATION: Majority of the respondents are positive towards the duration of the Six sigma programs. 36 employees are satisfied with the duration of Six sigma programs and 23 employees are highly satisfied. 15 employees are neither satisfied nor dissatisfied and remaining 26 employees are not satisfied with the same.

What is the selection criterion for Six sigma?

  1. By the department
  2. By the superior
  3. By the company
  4. Don’t know

INTERPRETATION: According to the graph, 42 respondents has chosen the selection criteria for Six sigma by the department, 25  respondents  by the superior, 21 respondents by the company and the remaining 12 respondents don’t know about the selection criterion for Six sigma.

Do you get trained periodically in six sigma methods on quality ?

  1. Yes
  2. No

INTERPRETATION: From the above chart, it is observed that 68% of the respondents will not train regularly while only 32% IT given Six sigma regularly.

Are you aware about the Six sigma objective which is being selected?

  1. Yes
  2. No

INTERPRETATION: According to the pie chart, 73% of the respondents are aware of the Six sigma objective while 27% of the respondents are not aware of the Six sigma objective.

Is your feedback on Six sigma modules considered by the management?

  1. Yes
  2. To some extent
  3. No
  4. Not aware of

INTERPRETATION: According to the pie graph, only 38% of the feedback on Six sigma module has been considered by the management, 34% to some extent. The remaining 28% feedback has put-off.

Does Six sigma help you in improving skills and tactics for effective execution of job?

  1. Yes
  2. To some extent
  3. No

INTERPRETATION: Six sigma is a systematic development of the knowledge, skills and attitudes required by employees to perform adequately on a given task or job. According to the graph, only 68% of the respondents are benefited through the Six sigma program, 26% of the respondents to some extent. The remaining 6% did not gain any skills through the Six sigma program.

What is the support you receive from your immediate reporting officer in the form of feedback while implementing Six sigma inputs?

  1. Good
  2. Moderate
  3. Poor
  4. No support at all 

INTERPRETATION: According to the graph, 46 respondents received good support from immediate reporting officer, 36 respondents get moderate support. The remaining 18 respondents did not receive any support for the immediate reporting officer.

How much does Six sigma help in your knowledge development?

  1. Greatly
  2. To some extent
  3. A little bit
  4. Not at all

INTERPRETATION: According to the survey, the Six sigma and development program is productive only for 100 respondents in which 24 respondents feel greatly and 42 respondents to some extent. A little bit of knowledge was gained by 26 respondents and for the remaining 8 respondents it is waste of time and worth.

What is your confidence level to face any higher responsibility after the Six sigma?

  1. Highly confident
  2. Confident
  3. Some confident
  4. Less confident
  5. No change in confidence level

INTERPRETATION: According to the graph, the Six sigma helped for 81 respondents to face any higher responsibility person in the organization. 10 respondents are somewhat confident and for remaining 9 respondents the level of confidence is same as before the Six sigma.

Your opinion about the relevancy of course syllabus (or Six sigma topics)

  1. Much relevant
  2. Relevant
  3. A little bit relevant
  4. Not at all relevant
  5. Can’t say

INTERPRETATION: According to the graph, 21 respondents are much relevant, 35 respondents are relevant, 29 respondents are a little bit relevant with the Six sigma topics. For remaining 15 respondents the course syllabus/Six sigma topics are irrelevant.

What are the facilities provided during Six sigma?

a.LCD

b.OHP

  1. Books
  2. Audio
  3. Any other

INTERPRETATION: According to the graph, 15 respondents are trained with LCD, 13 respondents with Audio,12 respondents with OHP, 5 respondents with books and the remaining 55 respondents with other facilities.

What is your level of satisfaction on the facilities provided during Six sigma?

  1. Highly satisfied
  2. satisfied
  3. Neither satisfied nor dissatisfied
  4. Not satisfied
  5. Not at all satisfied

INTERPRETATION: According to the graph, 39 are highly satisfied and 30 are satisfied with the facilities provided during the Six sigma. Only 13 respondents are dissatisfied with the facilities provided during the Six sigma. The remaining 18 respondents showed a neutral response

How is the trainer’s theoretical knowledge?

  1. Excellent
  2. Fair
  3. Good
  4. Satisfactory
  5. Poor

INTERPRETATION: From the above graph, it is noticed that except 3 respondents the remaining respondents are satisfied with the theoretical knowledge of the trainer’s.

Are you satisfied with the relevant examples during Six sigma?

  1. Highly satisfied
  2. Satisfied
  3. Neither satisfied nor dissatisfied
  4. Not satisfied
  5. Not at all satisfied

INTERPRETATION: Half of the respondents are satisfied with the relevant examples used during the Six sigma period while 17 are dissatisfied with the relevant examples used during the Six sigma period. The remaining 28 respondents showed a neutral response.

How did you feel about the freedom given to you in expressing and clarifying doubts?

  1. Fair
  2. Good
  3. Satisfactory
  4. Not satisfactory
  5. No freedom at all

INTERPRETATION: According to the graph, 38 respondents feel satisfied, 29 respondents feel good and 18 respondents feel as fair with the freedom given in expressing and clarifying the doubts by the trainer. The remaining 15 feel that they have not given enough freedom to express and to clarify.

What is your level of satisfaction of the reading material provided to you during the Six sigma period?

  1. Highly satisfied
  2. satisfied
  3. Neither satisfied nor dissatisfied
  4. Not satisfied
  5. Not at all satisfied

INTERPRETATION: Among the respondents, 45 respondents are not satisfied with the reading material provided during the Six sigma period only 25 respondents are satisfied with the reading material. The remaining 30 respondents showed a neutral response.

According to you, what is the level of effectiveness of Six sigma conducted in your organization?

  1. Highly effective
  2. Highly ineffective

INTERPRETATION: According to the graph, 16 respondents feel highly effective, 32 respondents feel moderately effective, 24 respondents feel neutral, 17 respondents feel as less effective and 11 respondents are not all effective regarding the Six sigma program conducted in the organization.

FINDINGS, SUGGESTIONS & CONCLUSION:

 FINDINGS

  1. About 53 % of respondents are very much satisfied with duration of the training program 15 employees are neither satisfied nor dissatisfied and remaining 26 employees are dissatisfied with duration consensus.
  2. According to the survey, 42% respondents has chosen the selection criteria for Six sigma by the department, 25 respondents  by the superior, 21 respondents by the company and the remaining 12 respondents don’t know about the selection criterion for Six sigma
  3. out of 100 respondents, majority of employees do not train regularly while only 32% IT given Six sigma regularly
  4. Six sigma is a systematic development of the knowledge, skills and attitudes required by employees to perform adequately on a given task or job. According to the graph, only 68% of the respondents are benefited through the Six sigma program, 26% of the respondents to some extent. The remaining 6% did not gain any skills through the Six sigma program
  5. out of 100 respondents, 82% of respondents extend their good support in reporting to their immediate officer. The remaining 18 respondents did not receive any support for the immediate reporting officer.
  6. about 64% of respondents feel that development program is productive  . A little bit of knowledge was gained by 26 respondents and for the remaining 8 respondents it is waste of time and worth.
  7. As per the survey, the Six sigma helped for 81 respondents to face any higher responsibility person in the organization. 10 respondents are somewhat confident and for remaining 9 respondents the level of confidence is same as before the Six sigma.
  8. majority of respondents are satisfied with the facilities provided during the Six sigma. Only 13 respondents are dissatisfied with the facilities provided during the Six sigma. The remaining 18 respondents showed a neutral responds.
  9. 48 respondents take effective stand towards poll, 24 respondents feel neutral, 17 respondents feel as less effective and 11 respondents are not all effective regarding the Six sigma program conducted in the organization.
  10. 15 respondents are trained with LCD, 13 respondents with Audio,12 respondents with OHP, 5 respondents with books and the remaining 55 respondents with other facilities.

 SUGGESTIONS

  1. organization need to use number of measurement and approaches to establish current performance.
  2. organization need to use appropriately a number of basic analysis tools and techniques to establish the root cause of a problem.
  3. Understand key lean concepts and tools, when and how to apply them to drive improvements
  4. Recognize the difference in approach and techniques for incremental and redesign improvement strategies and know how to decide on the correct approach.
  5. Establish ongoing process controls and process governance structures
  6. Decisions in my department are made with the input from people who IT affected by the decision
  7. By this study we can suggest to use Value Stream Mapping to show the linkage between merits and worth in training
  8. There can be projects like creating self-learning and evaluation modules for the employees
  9. It is recommended that the whole population of trainers in the department undergo a survey tackling on issues of morale and how they feel things can change for the better

CONCLUSION

A study on employee training using six sigma approach at IT Companies.  It comprises of a dynamic and enthusiastic team determined to accomplish the vision of the companies long term and short term goals.

An organization needs to frame its policies in a way that they are accepted by its internal customers and  there by achieve higher turn productivity.

Employee training program at different levels in the organization depends upon the experience of the employee considering there feedback at various levels  in the organization six sigma helps us in achieving  required standards for the organization in short period.

Therefore, employee training program using six sigma is of much essence in an organization and it has considerable impact on the performance and the top management should also take care of various measures and strategies to enhance the employee training program.

Encryption and Decryption of Data on Images Android Project

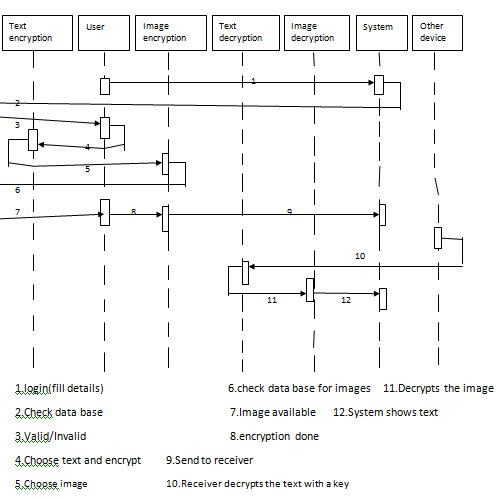
Android is a software platform and operating system for mobile devices. This is a project that is used to perform secret data transmission by performing encryption of text on images. The sender uses a key to perform encryption and the same key is given to the receiver to decrypt and obtain the data.

INTRODUCTION

Encryption of data on images provides a safe and secure transmission of data between the sending and receiving party.
The data/text which the sender wants to transmit is selected first and then an image is chosen from the current mobile device.
The chosen text is then encrypted in the image such that the data is not visible to any third party.
After encryption is performed, the image is sent to receiving party and the receiver decrypts the data using the key given by the sender.
This decryption process can only be performed by an authenticated receiver using this application.

OBJECTIVE

Main objective of this application is to provide a secure and secret transmission of text by encrypting it on an image using a key and which can only be decrypted by by an authenticated receiver using the same key on the same application.

KEY FUNCTIONALITY

• Start
• Chosen text/retrieve data from current device
• Browse an image from the device
• Encrypt the chosen text onto the image
• This image is sent to the receiver
• Receiver now decrypts the data

SOFTWARE AND HARDWARE REQUIREMENTS:

Java, JDK, Android SDK, My Eclipse
Android Mobile Device

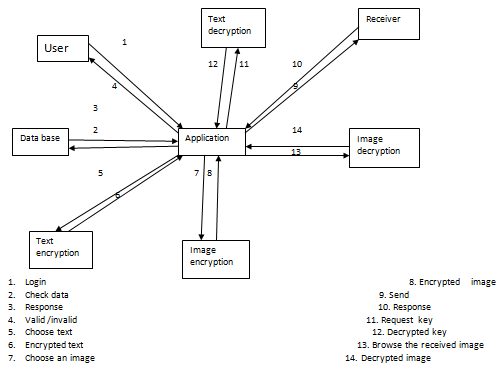
Data Flow Diagram:

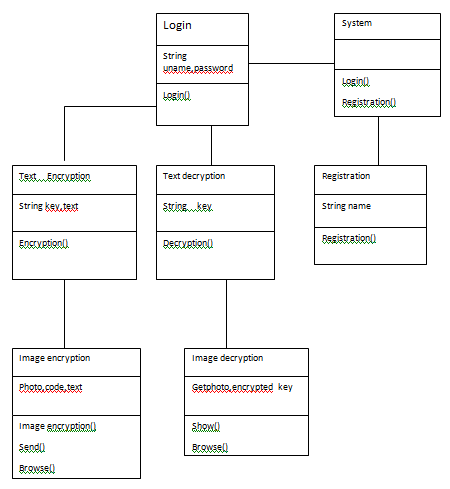
Class Diagram:

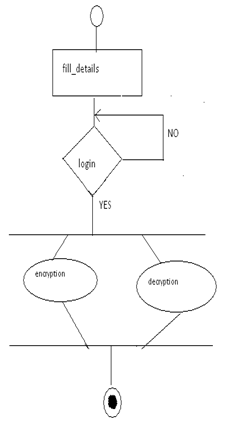
Activity Diagram:

Sequence Diagram:

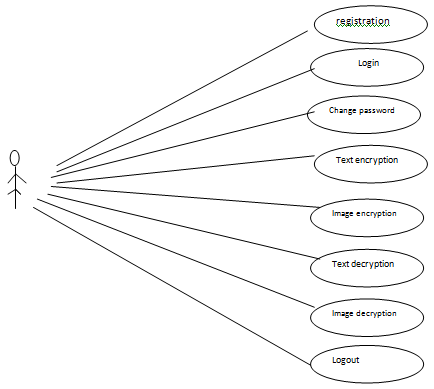
Use Case Diagram:

Collaboration Diagram:

INTRODUCTION

Existing system with limitations

The perspective of data security, which has always been an important aspect of quality of service, Cloud Computing inevitably, poses new challenging security threats fornumber of reasons.
Encryption of data/text was previously done using hash and cryptographic algorithms, which is written in binary form. Such encryption techniques are visible in a specific form and the intruder who is aware of binary text formats can easily read the text.
In those times it provided a lot of security but as technology progressed many hackers also came into existence and it could not provide security upto that extent.

Proposed system with features:

In this project we used many techniques to encrypt and make the data in-visible to any one(not even to the receiver). We used LSB (Least Significant Bit) format, stenography and cryptographic techniques to encrypt the data and the data/text being encrypted on an image will not be visible.

The sender will use a key for security reasons and the same key should be used by receiving party to decrypt the image and obtain the text written on it.
The image on which data encryption is being performed can be chosen from the existing device and after all the process completes, that image can be sent through Bluetooth or mail or google drive e.t.c.,

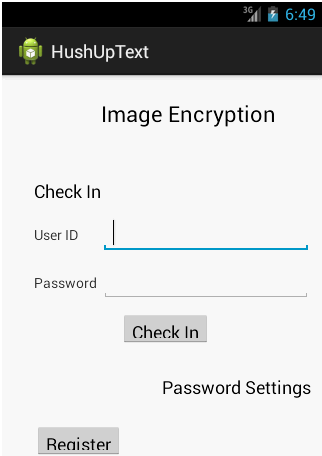
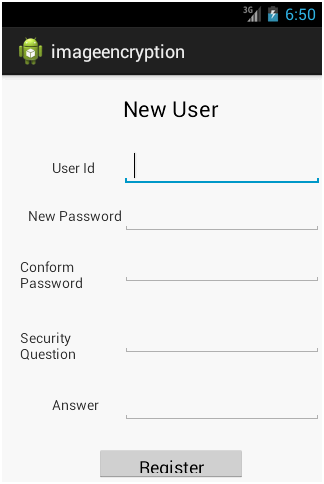
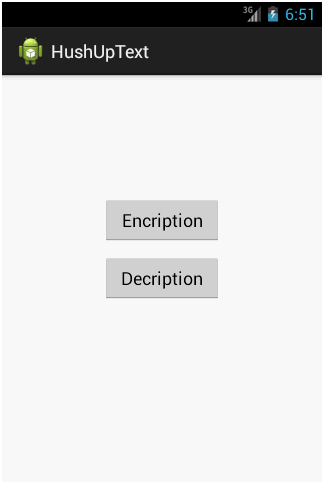
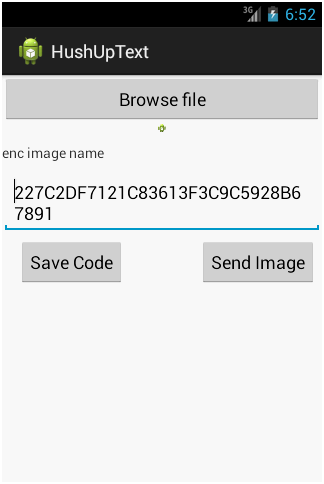
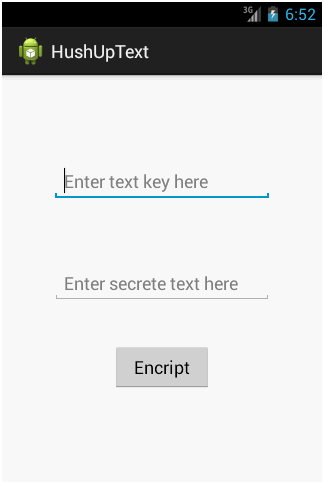
Output Results:

Download Encryption and Decryption of Data on Images Android Project Code, Project Report Documentation.

Event Management System Android App

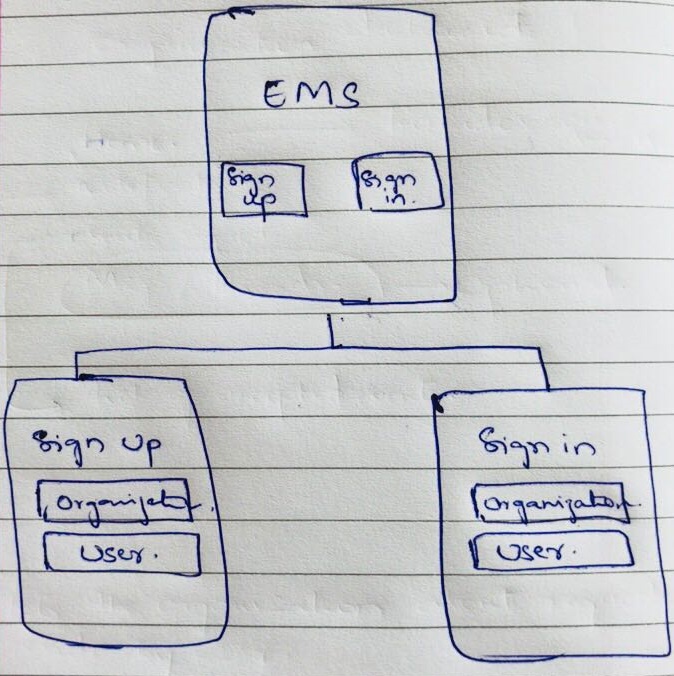
The main purpose of this Event management system android app is to provide the best event management application at an affordable price and time.

Users involved in this:

  • Admin
  • User
  • Organization

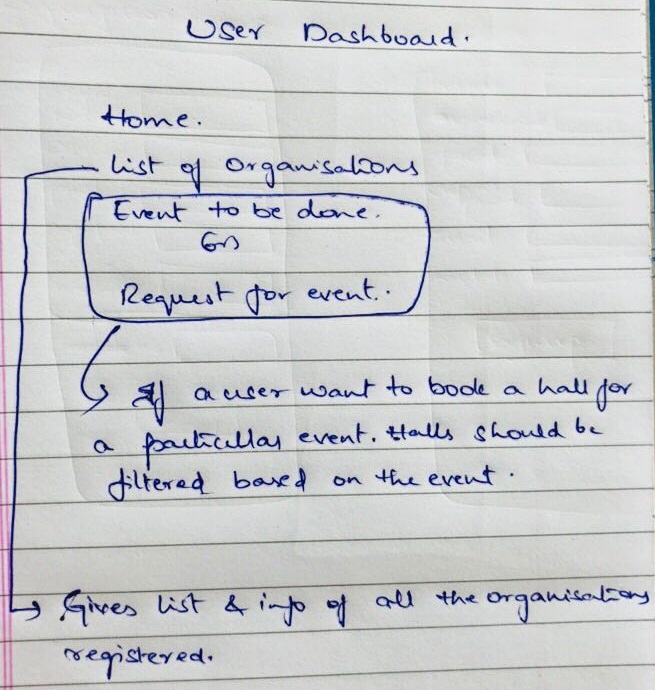
User:

The user sends a request regarding an event with an estimated amount and the work to be done

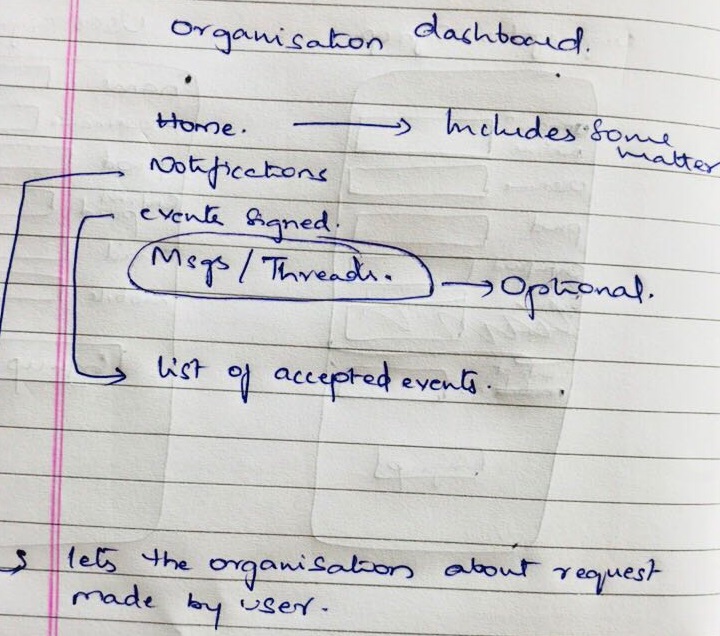
Organization:

organization if satisfied with the amt quoted accepts the request sent by the user and will be ready to do the event, if not satisfied will quote a better price and send it to the user who sent the request.

Before this, the organization should be registered.

Admin:

Organization registration will be handled by the admin. He/she can add or delete the organization list.

On the whole, the admin manages the organization list.

Download Online Event Management System Academic Project, which is developed in PHP, And MySQL database with HMTL, CSS, PHP, and Javascript.

Improving Robustness in AD-HOC Network by Detecting Malicious Node

Existing System:

  1. Due to wireless nature, the malicious nodes can easily gain access with the wireless links
  1. Once the malicious node gain the access, they can interrupt the data communication
  1. The malicious nodes can overhear / overwrite /  manipulate / drop the packets
  1. These malicious nodes degrades the network performance.

Proposed System:

  1. In order to detect malicious nodes, we have proposed an ID-based light-weight cryptographic protocol using authentication technique.
  1. This is light-weight mechanism, which means no complex calculations are required.
  1. The proposed technique works on the cryptographic one-way hash function and doesn’t include any cryptographic high computation operations like pairing as well as exponentiation.
  1. In this method, some random nodes are assumed as Temporary servers.
  1. Each node in the network possess an unique ID
  1. The sender node generates a key pair and send the data to Temporary server.
  1. This server verifies the sender authenticity and transmit the data to receiver.
  1. If the authenticity is not valid, then the sender node would be marked as MALICIOUS .

Enhancement:

  1. In order to segregate attackers from participating in network activities in future, we are proposing a CERTIFICATE REVOCATION method.
  1. According to this, the network is divided into different clusters and CH nodes are elected.
  1. These CH nodes keep maintaining of the Certificates  / keys of each its member nodes.
  1. if any node found as MALICIOUS, then the node’s certificate would be immediately revoked.
  1. without a valid certificate / keys, the malicious nodes cannot communicate with the network in future.

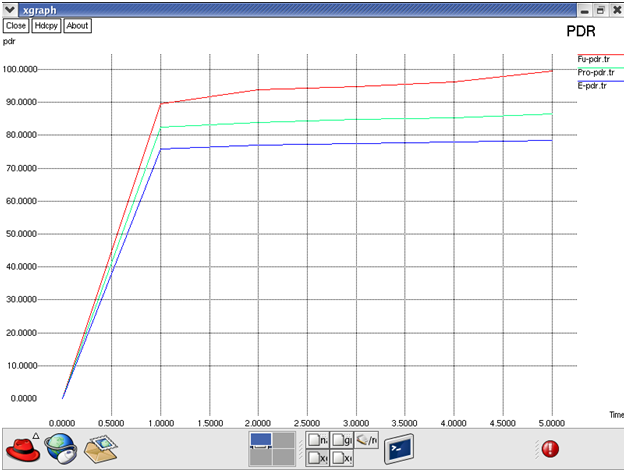
Simulation Results:

A cluster-based certificate revocation scheme is able to revoke malicious nodes certificate quickly on the basis of only one vote from the neighbor. In this system, CA maintains two different lists, warning list and black list, to keep track on the malicious nodes so as such nodes cannot take part in certificate revocation.

Graphs:

Fig: PDR

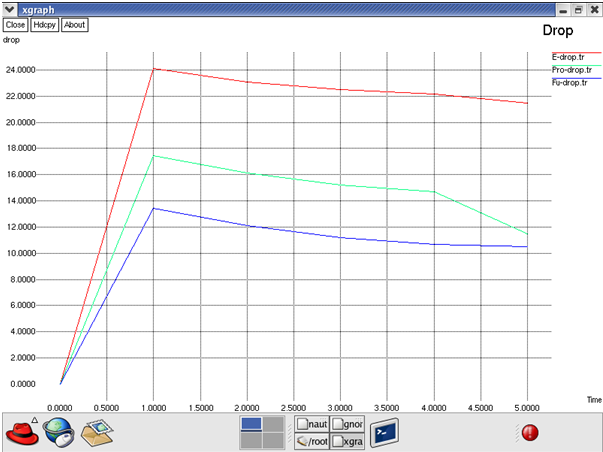
Fig: Drop

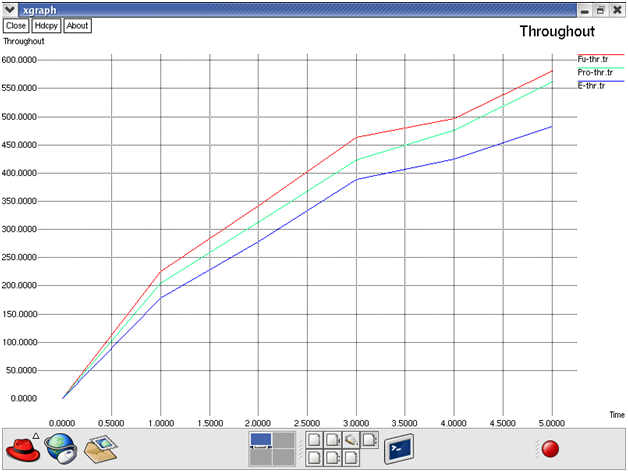
Fig: Throughout

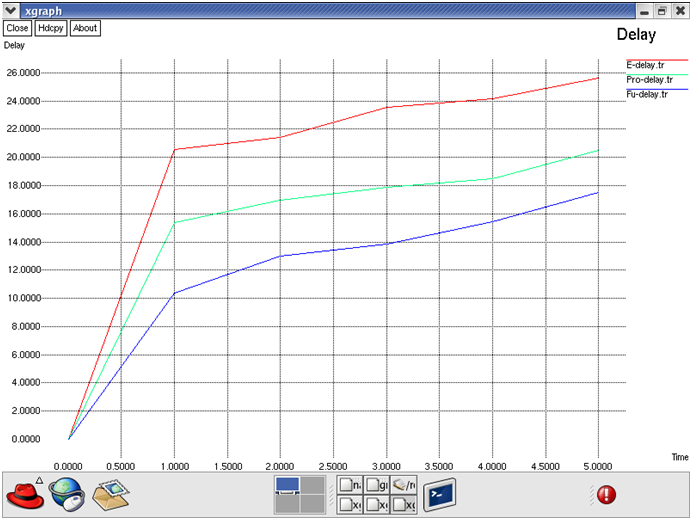
Fig: Delay

Hardware Requirements:

System:    Pentium IV 2.4 GHz.

Hard Disk:     50 GB.

Floppy Drive:  1.44 Mb.

Monitor:         18 VGA Color.

Mouse:            Logitech.

Ram:              2048 Mb.

Software Requirements:

Operating system:    Ubuntu 14.04/Red Hat Linux9/Linux Mint

Coding Language:    otcl, c++

Tool:                        Ns-2.34/Ns-2.35 

 Download This Improving Robustness in AD-HOC Network by Detecting Malicious Node NS2 project Code

Analysing User Behaviour In Social Network At Various Time Intervals

Abstract:

With the increase of internet users and applications like social networks and multimedia sharing websites users are spending much of their time of sharing information with users and even using these applications for business purpose. With increase of this usage there are many advantages of improving services for users by designing effective system for analyzing users behavior. In this system users intention is calculated using intention serialization analysis based on their interaction on social network. In this system each users interaction is calculated by storing each users sessions and respective interest of that user at that point of time and store entire details in to database. Based on the users data at different time intervals using novel algorithm calculation of user behavior is done. User behavior is useful for providing services like advertisements to users at respective time. As user behavior and interest changes from time to time design a system which can accurately analyze behavior at respective time is useful for providing services.

EXISTING SYSTEM: 

  • Inside any social media network each users behavior changes with time and what type of data is shared on social network. As each user has different roles and view different type of topics each day so finding users behavior and using those details for effective service is a challenging task.
  • There are many previous works which used many techniques to provide better solution for finding user intention one of them is considering surrounding users interests who are friends to specific user and considering common interest and user interest in that circle.

DISADVANTAGES:

  • Just by considering surrounding users or common friends interest and specific user interest in that group cannot provide accurate result. With time user behavior will change so existing system will not work in all scenarios.

PROPOSED SYSTEM: 

  • In order to get accurate interest and behavior of each user at that point of time there is need to use data related to user behavior of each user in social network. Using this data we can get sequence of interests users is searching on social network and by using users’ behavior pattern analysis and mining algorithm user behavior can be calculated. 

ADVANTAGES: 

  • By using behavior pattern analysis algorithm it is easy to know each user intention at that point of time.
  • By using this user analysis data it will be easy to advertise or share information to user with specific data.

SYSTEM REQUIREMENTS:

HARDWARE REQUIREMENTS: 

  • System : Pentium Dual Core.
  • Hard Disk : 120 GB.
  • Monitor : 15’’ LED
  • Input Devices : Keyboard, Mouse

SOFTWARE REQUIREMENTS: 

  • Operating system : Windows 7.
  • Coding Language : JAVA/J2EE
  • Tool : Netbeans 7.2.1
  • Database : MYSQL

Project Code & Database, Documentation will be uploaded soon.